Deep Learning Is a Specialized Kind of Neural Network
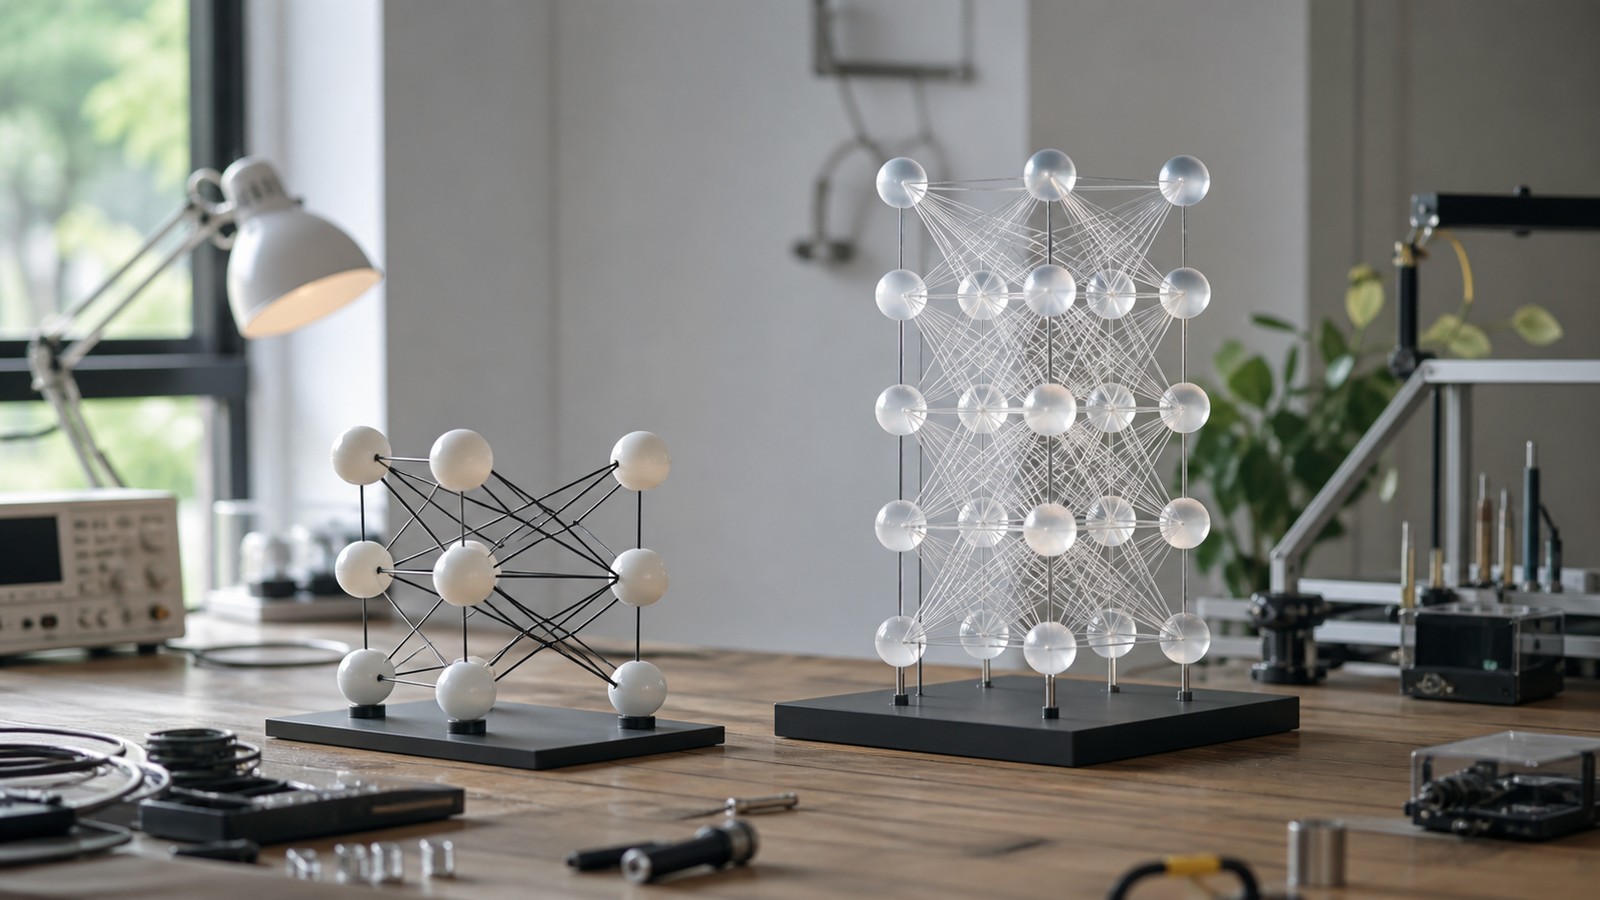
Deep learning and neural networks are related, but the terms are not identical. A neural network is a model structure inspired by connected layers of simple units. Deep learning usually refers to neural networks with many layers that can learn complex patterns from large datasets. The difference matters because not every neural network is deep, and not every AI problem needs a deep model. The right choice depends on data, complexity, interpretability, compute, and the decision being made.
Neural Networks Are the Broader Idea
A neural network is a model made of connected units that transform inputs into outputs. The units are arranged in layers and adjusted during training.
Simple neural networks may have only a few layers. They can still learn useful patterns when the task is modest and the data is structured.
Deep Learning Uses More Layers
Deep learning usually means neural networks with many layers. These layers can learn increasingly abstract representations of data.
The depth helps with images, speech, language, signals, and other complex inputs. It also increases training demands.
Layers Transform Information
Each layer receives information from the previous layer and transforms it. Early layers may learn simple patterns, while later layers combine them into more complex ones.
This layered structure is why deep models can handle rich data. The model builds its own internal features during training.
Training Adjusts Weights
Neural networks learn by adjusting weights. The training process compares predictions with expected outputs and updates the weights to reduce error.
This requires examples and an objective. Poor labels or unclear goals can teach the network the wrong pattern.
Activation Functions Add Flexibility
Activation functions let networks learn nonlinear relationships. Without them, stacked layers would be much less powerful.
Nonlinearity helps models capture curves, thresholds, interactions, and complex signal behavior.
Deep Models Need Data
Deep learning often needs more data than simpler models. Large models can learn rich patterns, but they can also memorize weak or biased datasets.
Data quality matters as much as size. More examples do not help if they do not represent the real task.
Compute Requirements Can Be High
Deep models may require GPUs, specialized hardware, longer training time, and careful deployment planning.
A smaller neural network or traditional model may be better when compute, latency, or power is limited.
Feature Learning Is a Strength
Deep learning can learn features automatically from raw or lightly processed data. This is useful for images, audio, text, and complex signals.
Automatic feature learning does not remove the need for domain knowledge. Data collection, labels, and evaluation still matter.
Simple Models Can Still Win
Some problems are best solved with simpler models. If the data is small, structured, or well understood, a deep model may add complexity without benefit.
Model choice should be based on performance, reliability, cost, and interpretability. Bigger is not automatically better.
Overfitting Is a Risk
A neural network can learn training examples too closely and fail on new examples. This is overfitting.
Validation data, regularization, simpler models, and better data can help. The test is performance on examples the model has not memorized.
Interpretability Can Be Hard
Deep networks can be difficult to explain because many layers and weights contribute to the output.
Interpretability tools can help, but high-impact decisions may still need extra review. Users should know the limits of explanation.
Signals Need Careful Evaluation
Signal models should be tested on noise, drift, device variation, rare events, and real deployment conditions.
A deep model that works on clean data may fail when sensors, channels, or environments change.
Transfer Learning Can Help
Transfer learning uses a model trained on one large task as a starting point for another task.
This can reduce data needs and training time, but the source task must be relevant enough. Transfer still needs validation.
Deep Learning Supports Many Signal Tasks
Deep models can support speech recognition, image analysis, anomaly detection, sensor fusion, channel estimation, and pattern classification.
The model should be matched to the task. Deep learning is a tool, not a default answer.
What to Check Next
Teams should check data size, label quality, task complexity, compute limits, interpretability needs, and deployment constraints.
They should compare deep models with simpler baselines. The deep model should earn its added cost.
Deployment Notes
Deployment should include monitoring for drift, performance changes, latency, hardware limits, and failure cases.
Model updates should be tested carefully. A new deep model can improve one group of cases while weakening another.
Practical Review
A practical review asks whether deep learning improves the decision enough to justify its complexity.
If the answer is unclear, a simpler neural network or traditional model may be the better engineering choice.
Final Takeaway
Deep learning is a powerful subset of neural network methods, not a separate magic category.
The best choice depends on evidence: data quality, task complexity, deployment limits, and measurable improvement over simpler approaches.
Architecture Should Match Data
Different neural network architectures fit different data types. Convolutional networks, recurrent models, transformers, and simple feed-forward networks each have different strengths.
Architecture should follow the task. A model chosen because it is fashionable may not be the best model for the signal.
Baselines Keep Deep Learning Honest
A deep model should be compared with simpler baselines. If the simple model performs nearly as well, it may be easier to deploy and explain.
Baselines help teams avoid unnecessary complexity. They also prove whether deep learning adds real value.
Deployment Is Part of Model Choice
A model that trains well but runs too slowly, costs too much, or cannot be monitored may be a poor practical choice.
Deployment constraints should be considered before training becomes expensive. Engineering fit matters.
Final Model Review
A final review should ask whether deep learning improves accuracy, robustness, or workflow enough to justify the data and compute required.
The strongest model is not always the deepest one. It is the model that serves the decision reliably.
Depth Adds Representation Power
Depth lets a model build patterns in stages. Early layers may detect simple shapes, tones, or signal edges, while later layers combine them into richer concepts.
This is why deep learning works well for complex data. The model can learn intermediate representations instead of relying only on hand-built features.
Data Volume Changes the Tradeoff
Deep models can benefit from large datasets, but small datasets may not justify their complexity.
When data is limited, simpler models, transfer learning, or feature engineering may be more reliable. Model size should match evidence.
Training Stability Needs Care
Deep networks can be harder to train than shallow models. Learning rate, initialization, normalization, and architecture choices can affect results.
Training should be monitored carefully. A model that fails to converge or learns unstable patterns may need redesign.
Validation Must Be Honest
Deep learning results can look strong when validation data is too similar to training data.
Evaluation should include held-out examples, difficult cases, and deployment-like conditions. Honest validation protects against overconfidence.
Signal Models Need Robustness
Signals often include noise, missing values, drift, and device variation. Deep models should be tested against those realities.
A model that only works on clean examples may fail in the field. Robustness is part of model quality.
Interpretability Depends on Use
Some use cases can tolerate limited interpretability, while others require clear reasons for decisions.
The more important the decision, the more explanation and review matter. Deep learning should fit the accountability need.
Maintenance Does Not End at Launch
Deep models need monitoring after deployment. Data drift, label drift, hardware changes, and new user behavior can weaken performance.
Maintenance includes retraining, evaluation, rollback, and comparison with prior versions. The model is part of an ongoing system.
Final Deep Learning Takeaway
Deep learning is valuable when layered representation improves real performance enough to justify complexity.
It should be chosen because evidence supports it, not because the name sounds more advanced.
Neural Networks Can Be Shallow
A neural network does not need many layers to be useful. Shallow networks can work well for structured inputs and smaller tasks.
This is why the vocabulary matters. Neural network is the broad category, while deep learning usually means larger layered networks.
Deep Learning Can Learn Raw Patterns
Deep models can sometimes learn directly from raw signals, images, text, or audio. This can reduce the need for hand-built features.
Raw learning still needs good data and evaluation. The model may learn the wrong shortcut if the dataset is biased or narrow.
Regularization Helps Generalization
Regularization methods reduce overfitting by discouraging overly fragile patterns. Dropout, weight decay, augmentation, and early stopping are common examples.
The goal is not just to perform well on training data. The model must handle new examples reliably.
Explainability Tools Have Limits
Tools can highlight features, examples, or input regions that influenced a model, but they do not always provide a complete explanation.
Teams should treat explanations as evidence to review, not automatic proof that the model is correct.
Monitoring Should Include Subgroups
A model may perform well overall and poorly on certain devices, users, signal types, or environments.
Subgroup monitoring helps catch uneven performance. This matters when deployment conditions are diverse.
Final Neural Network Check
Before choosing deep learning, teams should compare accuracy, robustness, cost, latency, interpretability, and maintenance burden.
After deployment, they should keep comparing outcomes with simpler baselines and real user needs.
Deep Models Need Good Objectives
A deep model optimizes the objective it is given. If the objective does not match the real decision, the model may improve the wrong thing.
Teams should define success carefully. Accuracy, recall, latency, fairness, stability, and cost may all matter depending on the task.
Data Augmentation Can Help
Data augmentation creates useful variation in training examples. Images may be cropped, audio may include noise, and signals may be shifted or scaled.
Augmentation can improve robustness when it reflects realistic variation. Unrealistic augmentation can teach the model patterns it will never need.
Pretrained Models Need Validation
Pretrained deep models can save time, but they still need validation on the target task.
A model trained on broad data may not understand a specific signal environment. Local testing remains essential.
Neural Networks Need Monitoring
A deployed neural network should be monitored for input drift, output drift, errors, latency, and user impact.
Monitoring makes the model accountable after launch. It helps teams catch problems before they become normal.
Better Models Serve Better Decisions
The purpose of a neural network is not to be deep or complex. The purpose is to improve a decision, prediction, classification, or control process.
That practical standard keeps model selection grounded. The best model is the one that works reliably for the real job.
Model Size Should Match Risk
A high-risk task may justify more testing, monitoring, and model complexity. A low-risk task may be better served by a smaller model.
Risk should shape the engineering process. The model choice should reflect consequence, not just technical ambition.
Final Deep Learning Review for Teams
Teams should choose deep learning when it clearly improves outcomes and can be maintained responsibly.
If a simpler model is easier to explain, cheaper to run, and nearly as accurate, that simpler option may be the more reliable engineering decision.
Good Comparisons Use the Same Test
Deep and shallow models should be compared on the same data, same metrics, and same deployment constraints.
That makes the comparison fair. It shows whether depth really improved the result or only changed the experiment.
Practical AI Needs Maintenance
A neural network is not finished when training ends. It needs monitoring, documentation, version control, and a plan for failures.
That maintenance work is part of responsible AI. It keeps the model useful after the first successful test.