AI Reads Language by Turning Text Into Signals
AI language systems read text by turning words, phrases, structure, and context into patterns a model can compare. They do not understand language the way people do, but they can learn useful relationships from examples. Tokens, embeddings, syntax, intent clues, sentiment, entities, and context windows all become signals that help the system classify, summarize, translate, retrieve, or generate text.
The Task Comes First
AI language signal analysis should begin with the task the language model needs to support. The goal is to interpret text patterns without pretending the model has human understanding.
That goal decides which inputs matter, which metrics fit, and how much review is needed.
Inputs Shape Learning
tokens, embeddings, grammar, intent clues, sentiment, entities, and context can all affect how the system behaves.
The model cannot learn what the input does not show. Input quality sets the ceiling for useful output.
Patterns Need Examples
A model learns from examples rather than from broad understanding.
The examples define the patterns the model can notice. Missing or narrow examples create weak coverage.
Features Make Data Usable
Features are the pieces of information the model can compare.
Good features preserve useful meaning. Weak features hide the pattern or add noise.
Labels Guide Supervised Learning
When labels are used, they tell the model what output it should learn to produce.
Poor labels teach poor behavior. Label rules should be clear enough for consistent training and evaluation.
Weights Change During Training
Weights control how strongly different parts of the model influence the output.
Training adjusts those weights. The model improves by reducing measured error across many examples.
Layers Transform Information
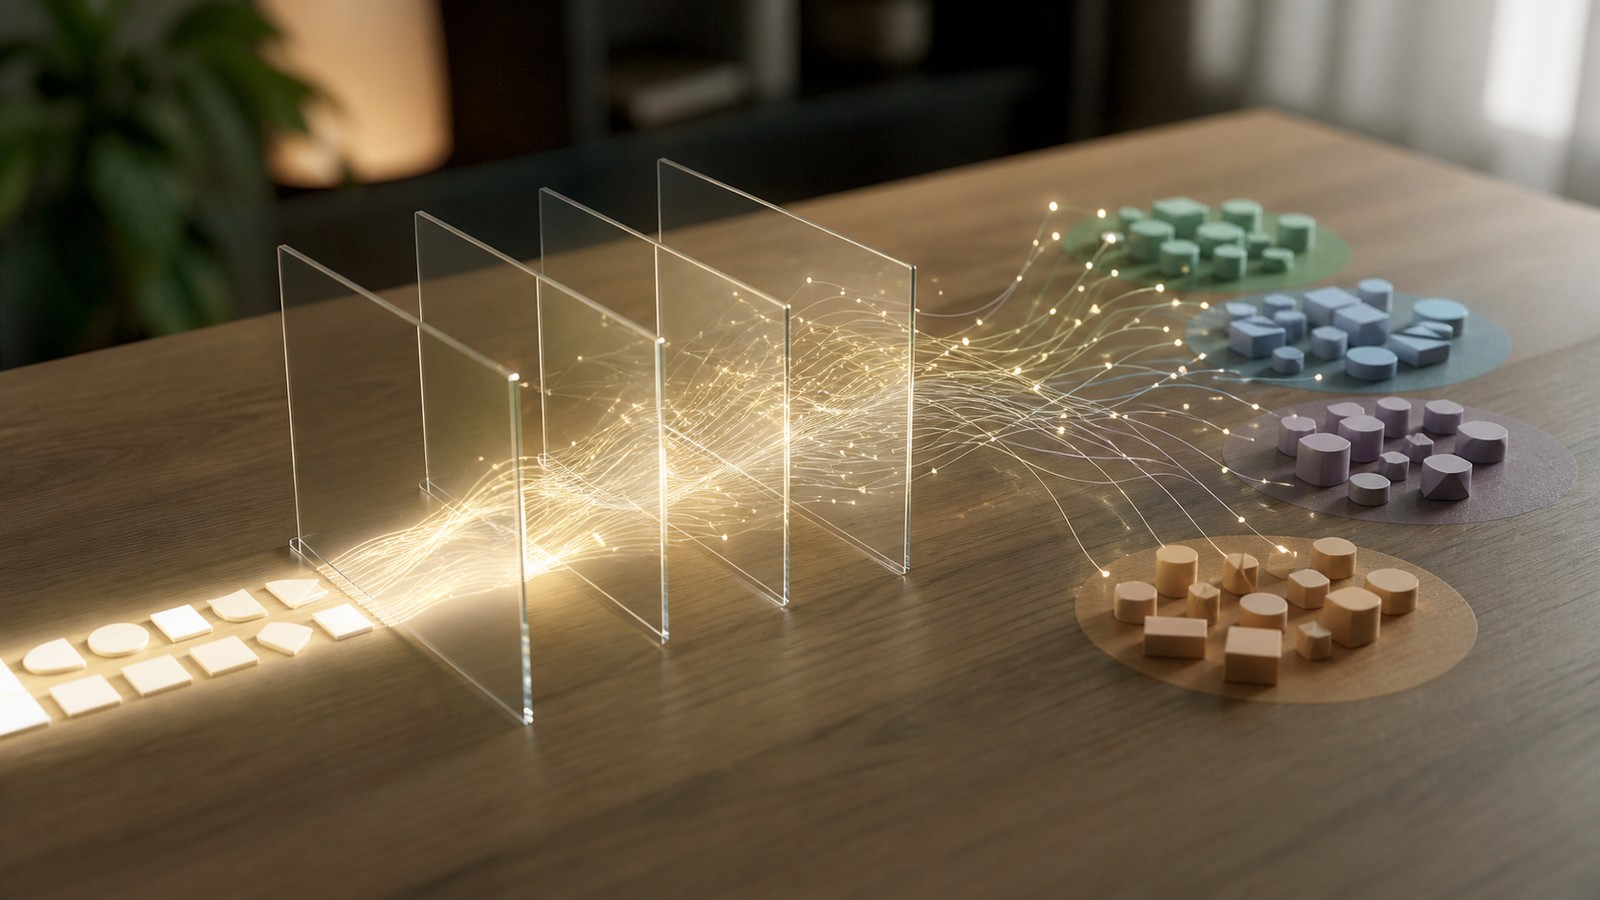
Layers transform inputs step by step. Earlier layers may capture simpler patterns, while later layers combine them.
This layered structure helps models handle complex data. It also makes explanation harder.
Activation Adds Flexibility
Activation functions let models learn nonlinear relationships.
Without them, many layered models would be much less useful. Nonlinear behavior helps with language, images, signals, and decisions.
Loss Measures Mistakes
A loss function turns mistakes into a number the training process can reduce.
The loss should match the real task. A model can optimize the wrong thing if the objective is poorly chosen.
Optimization Updates the Model
An optimizer decides how weights change after the model sees errors.
Learning rate, batch size, and update rules can all affect training. Settings should be tested rather than assumed.
Validation Checks Generalization
Validation data checks whether the model works beyond the examples used for training.
Good validation protects against overfitting. It shows whether the pattern is durable or memorized.
Test Data Should Stay Honest
A test set should be held back until model choices are mostly settled.
Using the test set too often turns it into another tuning tool. Honest testing protects trust.
Overfitting Is a Real Risk
Overfitting happens when a model learns training quirks instead of durable patterns.
Regularization, better data, simpler models, and careful validation can reduce that risk.
Underfitting Means Too Little Learning
Underfitting happens when the model misses important patterns.
The fix may be better features, better training, more data, or a more suitable architecture. Bigger is not always the answer.
Context Changes Meaning
The same input can mean different things in different contexts.
A model needs enough surrounding evidence to interpret the pattern correctly. Context windows and metadata can matter.
Confidence Needs Calibration
A confidence score should match real reliability.
Calibration helps users know when to trust the output and when to review. A high score should not be decoration.
Errors Should Be Studied
Errors are not just failures; they are clues about what the model does not handle well.
Error review can reveal missing data, weak labels, poor features, or unrealistic test conditions.
Segment Testing Finds Gaps
Overall performance can hide weak spots in certain groups, topics, devices, or input types.
Segment testing makes those gaps visible. It helps teams avoid false confidence.
Drift Changes Performance
Data changes over time. Language, user behavior, devices, tasks, and environments can all shift.
Monitoring catches drift. It shows when the model needs retraining, review, or recalibration.
Interpretability Helps Review
People need some way to understand why a model responded.
Interpretability tools can help, but they are not perfect explanations. They should support review, not replace it.
Human Review Still Matters
Some outputs should go to human review, especially when consequences are meaningful or evidence is uncertain.
Review rules should be planned before launch. They keep the model within its intended role.
Privacy Should Shape Data Use
Training and input data can contain sensitive information.
Privacy should guide collection, storage, access, and retention. More data is not automatically better.
Security Protects the Pipeline
Bad data, unauthorized changes, and insecure updates can damage model behavior.
Security should protect inputs, models, logs, and deployment paths. Trust depends on the full system.
Logs Make Outputs Traceable
Logs should preserve key inputs, model version, confidence, and output decisions when appropriate.
Traceable logs help teams investigate mistakes. They also support maintenance and audits.
Version Control Protects Comparisons
Model, data, feature, threshold, and prompt changes can all alter behavior.
Version control makes those changes visible. It helps teams compare old and new results fairly.
Metrics Need Balance
Accuracy alone rarely explains quality. Precision, recall, calibration, latency, cost, and user impact may all matter.
The metric set should match the task. A model should be judged by the decision it supports.
Baselines Keep Claims Honest
A baseline gives the model something to beat.
The baseline may be a simple rule, older model, or manual process. Complexity should earn its place.
Simple Models Can Win
A simpler model may be better when it is accurate enough, cheaper, faster, and easier to explain.
The best choice is the model that fits the task. Bigger does not automatically mean better.
Deployment Adds Constraints
A model that works offline may face latency, memory, cost, power, or integration limits after deployment.
Deployment constraints should be considered early. Practical fit matters.
Monitoring Continues After Launch
Launch is not the end of model work.
Monitoring tracks drift, failures, latency, and user impact. It shows when maintenance is needed.
Documentation Supports Handoffs
Documentation should explain purpose, data, metrics, limits, intended use, and review rules.
Good documentation helps future teams maintain the language model. It keeps the model from becoming a mystery.
Outputs Need Careful Wording
Outputs should describe what the model can support without overstating certainty.
Careful wording helps users respond appropriately. It prevents a score or label from sounding like absolute truth.
Action Rules Close the Loop
The output should connect to action rules such as review, accept, reject, compare, monitor, or escalate.
Action rules make the model useful. They turn prediction into workflow.
Good Systems Stay Humble
A good system reports what evidence supports and leaves room for uncertainty where evidence is limited.
That humility is practical. It makes AI language signal analysis safer and easier to trust.
Final Takeaway
AI language signal analysis is strongest when training, testing, explanation, and maintenance are treated as one system.
The goal is to interpret text patterns without pretending the model has human understanding. Strong AI depends on evidence that can be checked.
Examples Should Match Reality
Training and testing examples should resemble the conditions where the model will be used.
If examples are too clean or narrow, the language model may look stronger than it really is.
Difficult Cases Deserve Review
Difficult cases reveal where the model is uncertain, brittle, or missing context.
Those cases should guide better data, labels, and review rules.
Fallbacks Reduce Risk
When confidence is low or input quality is poor, the system should have a fallback path.
Fallbacks may include human review, a simpler rule, no action, or a request for more evidence.
Periodic Review Catches Drift
Periodic review checks whether examples, labels, metrics, and use cases still match current needs.
That review keeps AI language signal analysis from aging quietly.
Final Use Check
Before relying on the output, users should ask what evidence supports it, what remains uncertain, and what action follows.
That check keeps the system grounded in practical judgment.
Small Changes Can Matter
A small change in training data, labels, preprocessing, context, or threshold can change the output.
Small changes should be tested and documented. They can affect the language model more than users expect.
Scenario Testing Helps
Scenario testing checks behavior in realistic situations rather than only average examples.
Scenarios show whether the model handles ambiguity, missing context, and edge cases. They make testing easier to understand.
Bad Inputs Need Handling
The model should know how to handle missing, noisy, contradictory, or out-of-range inputs.
Input handling protects the output. It keeps weak evidence from looking stronger than it is.
Calibration Keeps Scores Honest
Calibration checks whether confidence scores match real outcomes.
A calibrated model helps users weigh evidence. A poorly calibrated one can make weak answers look certain.
Comparison Prevents Tunnel Vision
Model outputs should be compared with baselines, alternate explanations, or related checks.
Comparison prevents tunnel vision. It helps users avoid building a story around one attractive output.
User Feedback Needs Structure
User feedback is most useful when it is captured consistently.
Structured feedback can improve examples, labels, thresholds, and review rules. It turns use into learning.
Retesting Builds Confidence
A model that remains useful after retesting across time and conditions deserves more confidence.
Retesting helps separate durable patterns from luck. It also catches drift before users notice broad failure.
Ownership Keeps Quality Alive
Someone should own repeated errors, stale examples, and changing conditions.
Clear ownership keeps maintenance from becoming optional. It gives the model a real support path.
Plain Language Helps Users Act
Outputs should explain the result in plain language that matches the evidence.
Plain wording reduces overreaction. It helps users choose a next step without treating the model as unquestionable.
Final Evidence Check
A final evidence check asks whether the input, model output, confidence, and action all make sense together.
That check keeps AI language signal analysis disciplined. It helps the system support judgment instead of replacing it.
Data Boundaries Matter
The model should have clear boundaries around what data it was trained on and what conditions it was meant to handle.
Boundaries prevent misuse. They help users know when the language model is operating outside its strongest area.
Evaluation Should Include Hard Cases
Evaluation should include ambiguous, rare, noisy, and incomplete examples.
Hard cases show whether the model can handle real work. They also reveal where fallback rules are needed.
Latency Can Affect Usefulness
A model output may be accurate but still arrive too late for the workflow.
Latency should be measured where the model will run. Speed is part of practical quality.
Cost Should Be Visible
Models consume compute, storage, review time, and maintenance effort.
Cost should be visible when choosing an approach. A simpler model may be better when it solves the task well enough.
Release Notes Help Teams
Each meaningful model update should explain what changed and why.
Release notes make behavior easier to trace. They also help users understand new limits or improvements.
Long-Term Value Needs Care
Long-term value depends on keeping examples, labels, metrics, and review rules current.
Care after launch keeps AI language signal analysis useful. It prevents a working model from slowly becoming stale.
Final Practical Standard
The practical standard is whether the model helps users make a better next decision.
When that standard is met, the language model is useful. When it is not, more complexity is not the answer.