Machine Learning Models Learn Patterns From Examples
Machine learning models learn from data by finding patterns that help them predict, classify, recommend, detect, rank, or generate outputs. The learning process depends on examples, input features, labels or feedback, training objectives, and careful testing on data the model has not already seen. A model does not understand a problem the way a person does; it learns statistical relationships that can be useful when the data is representative and the goal is clearly defined.
Examples Define the Learning Space
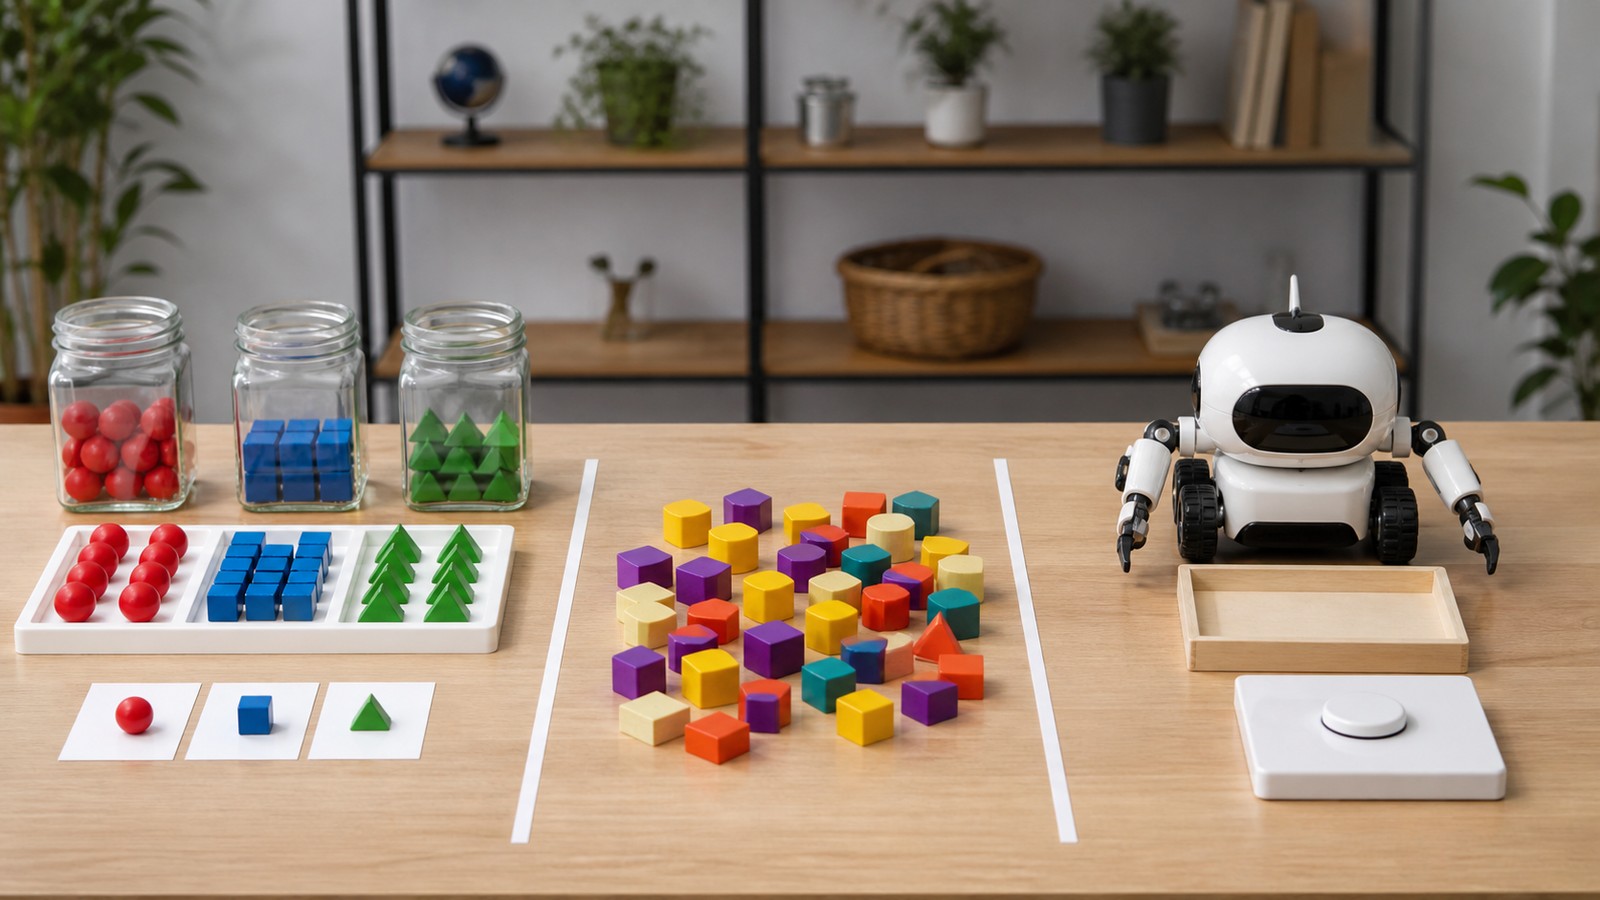
A model learns from examples. Those examples might be records, images, signals, text, transactions, clicks, or sensor readings.
The examples define what the model can notice. If important cases are missing, the model may look confident while remaining incomplete.
Features Describe Each Example
Features are the pieces of information the model receives. They may be raw values, engineered measurements, embeddings, or signals from another system.
Useful features make patterns easier to learn. Weak features can hide the real relationship even when the dataset is large.
Labels Provide Answers for Supervised Tasks
In supervised learning, labels tell the model the expected answer. A label may mark a category, value, event, or outcome.
Labels need to be consistent and meaningful. Noisy labels teach noisy behavior, and biased labels can create biased predictions.
Training Finds a Pattern
Training is the process of adjusting the model so its outputs better match the training examples. The exact method depends on the model type.
The model is not copying a rulebook. It is fitting a pattern that reduces error according to the objective it was given.
The Objective Guides Learning
The objective tells the model what it is trying to improve. It might reward accuracy, lower error, better ranking, or higher expected return.
A poorly chosen objective can produce the wrong behavior. The model may optimize the number while missing the practical goal.
Loss Turns Mistakes Into a Signal
A loss function measures how wrong the model is during training. That signal guides updates.
Different tasks require different loss choices. A forecast, classifier, recommendation system, and anomaly detector should not all be judged the same way.
Optimization Updates the Model
Optimization changes model parameters to reduce loss. It is the repeated step that turns examples into learned behavior.
The pace of optimization matters. Training can fail if updates are unstable, too slow, or trapped in a poor pattern.
Validation Checks Generalization
Validation data helps test whether the model works beyond the examples used for training. It is a guard against overfitting.
Good validation data should reflect real conditions. If validation is too clean, the model may look better than it is.
Test Data Gives a Final Check
Test data is held back until model choices are mostly settled. It gives a cleaner estimate of how the model may perform.
A test set should not be used repeatedly to tune decisions. Otherwise it stops being an independent check.
Overfitting Means Memorizing Too Much
Overfitting happens when a model learns training quirks instead of durable patterns. It may perform well on familiar data and poorly on new data.
Regularization, simpler models, more data, and better validation can help. The aim is useful generalization.
Underfitting Means Learning Too Little
Underfitting happens when the model misses important patterns. It may be too simple, poorly trained, or missing important features.
Solving underfitting requires diagnosis. Adding complexity is not always the right answer if the inputs or labels are the real problem.
Data Splits Must Be Honest
Training, validation, and test data should be separated in a way that reflects the real problem. Leakage between splits can inflate performance.
Time-series, user-level, and device-level data may need special splitting rules. Honest splits prevent false confidence.
Bias Can Enter Through Data
Data can reflect uneven history, missing groups, measurement limits, or past decisions. A model may learn those patterns and repeat them.
Bias checks should be part of evaluation. Performance should be examined across important subgroups and situations.
Metrics Shape Model Choice
Metrics show how well a model performs, but no single metric tells the whole story. Accuracy can hide weak performance on rare cases.
Precision, recall, error size, latency, stability, and calibration may all matter. The metric should match the decision.
Baselines Keep Progress Honest
A baseline is a simple model or rule used for comparison. It shows whether the machine learning model actually adds value.
Without a baseline, improvement is hard to judge. A complicated model should beat simpler options by enough to justify itself.
Feature Engineering Can Help
Feature engineering creates inputs that make useful patterns easier to learn. It may summarize time, frequency, behavior, location, or signal quality.
Modern models can learn some features automatically, but domain knowledge still helps. Good inputs often reduce unnecessary complexity.
Model Choice Depends on the Task
Decision trees, linear models, neural networks, clustering methods, and deep learning systems each fit different problems.
The best model is not always the newest model. It is the model that fits the data, goal, risk, and deployment constraints.
Training Data Can Become Outdated
Data changes when users, devices, markets, policies, or environments change. A model trained on old patterns may become stale.
Monitoring helps detect drift. Retraining may be needed when the world no longer matches the training data.
Prediction Is Not Understanding
A machine learning model may predict accurately without understanding cause. Correlation can still be useful, but it has limits.
Teams should be careful when using predictions to make causal claims. Some decisions need experiments or expert review.
Confidence Needs Calibration
Some models output confidence scores that do not match real reliability. A high score may still be wrong more often than expected.
Calibration checks whether confidence matches outcomes. This matters when people use scores to make decisions.
Errors Should Be Studied
Model errors are not just failures; they are clues. Error review can reveal missing features, weak labels, edge cases, or misunderstood goals.
Studying errors helps improve the system. It also shows where human review or fallback rules are needed.
Deployment Adds Constraints
A model that performs well offline may be too slow, expensive, or fragile in production. Deployment changes the practical requirements.
Latency, memory, uptime, monitoring, and integration all matter. Machine learning is part of a larger system.
Feedback Can Improve or Harm
Some systems learn from user feedback after launch. Feedback can improve the model, but it can also reinforce bad patterns.
Feedback loops should be watched carefully. The system should not reward shortcuts, spam, or unfair outcomes.
Documentation Supports Trust
Model documentation should explain data sources, intended use, limits, metrics, update plans, and known risks.
Documentation helps teams maintain the model and helps users understand where caution is needed. It makes learning systems easier to govern.
Practical Model Review
A practical review asks whether the model has enough data, clear features, honest evaluation, useful metrics, and a deployment plan.
It should also ask what happens when the model is wrong. Reliability includes failure handling.
Final Learning Takeaway
Machine learning models learn useful patterns from examples when the data, objective, and evaluation are aligned.
The strongest models are not just trained; they are tested, monitored, documented, and maintained as conditions change.
Sampling Changes the Lesson
The way examples are sampled can change what the model learns. Rare cases may disappear if the sample only reflects the most common situations.
Sampling should match the model's purpose. A system meant to catch unusual events needs enough unusual examples to learn from.
Class Imbalance Can Mislead
Class imbalance happens when one outcome is much more common than another. A model can look accurate by mostly predicting the common class.
Balanced metrics and careful evaluation help reveal this problem. Rare but important cases deserve special attention.
Preprocessing Must Be Consistent
Preprocessing changes raw data into a usable form. Scaling, cleaning, encoding, and filtering must be applied consistently.
Training and production should use the same steps. A mismatch can make a good model behave badly after launch.
Feature Leakage Inflates Scores
Feature leakage happens when training data contains information that would not be available during real use.
Leakage can make a model look excellent in testing and weak in production. Honest feature design protects evaluation.
Time Order Can Matter
Some data has a natural time order. Training on future information and testing on earlier cases can create unrealistic results.
Forecasting, signals, markets, and maintenance tasks often need time-aware splits. The test should imitate real use.
Human Decisions Affect Data
Historical data may include human choices, policies, habits, and errors. A model can learn those patterns whether or not they are fair or useful.
Teams should examine how the data was created. The collection process can be as important as the model algorithm.
Thresholds Turn Scores Into Actions
Many models produce scores rather than direct actions. A threshold decides when the score becomes an alert, approval, label, or recommendation.
Thresholds should be tuned to the cost of mistakes. A medical alert, spam filter, and maintenance warning need different tradeoffs.
Precision and Recall Trade Off
Precision measures how often positive predictions are correct. Recall measures how many true positives the model catches.
Improving one can reduce the other. The right balance depends on whether false alarms or missed cases are more costly.
Calibration Supports Better Decisions
A calibrated model gives probabilities that match real outcomes. If it says eighty percent, roughly eight out of ten similar cases should be true.
Calibration helps people use scores responsibly. It is especially important when a score influences risk decisions.
A/B Testing Can Confirm Value
Offline metrics do not always show whether a model improves a real workflow. A controlled rollout can measure practical value.
A/B testing should be designed carefully. It should protect users while checking whether the model changes outcomes in the intended way.
Monitoring Finds Drift
Model drift happens when input patterns or outcome relationships change. Drift can reduce performance even if the model has not changed.
Monitoring catches drift early. It shows when retraining, threshold changes, or data investigation may be needed.
Retraining Needs Discipline
Retraining can improve a stale model, but it can also introduce new problems. New data may contain errors or changed behavior.
A retrained model should be compared with the current version before release. Improvement should be measured, not assumed.
Fallback Rules Add Stability
Some cases should fall back to a rule, human review, or safe default. This is useful when data is missing or confidence is low.
Fallback behavior makes machine learning safer to operate. It defines what happens when the model should not decide alone.
Model Cards Can Help Teams
A concise model card can summarize purpose, data, metrics, limits, risks, and update plans. It gives teams a shared understanding.
This kind of documentation supports maintenance. It also helps new team members understand the model quickly.
Learning Systems Need Ownership
A model needs an owner after deployment. Someone must track performance, data changes, incidents, and update decisions.
Without ownership, model quality can decline quietly. Clear responsibility keeps the system healthy.
Good Models Serve a Workflow
A model should fit the workflow where its output is used. A prediction that arrives too late or lacks context may not help.
Workflow fit matters as much as score quality. Machine learning succeeds when it improves an actual decision process.
Practical Learning Is Iterative
Machine learning usually improves through cycles of data review, modeling, testing, deployment, and monitoring.
Each cycle should answer a specific question. Iteration works best when changes are small enough to evaluate clearly.
Learning From Data Requires Judgment
Data can guide a model, but people still choose the goal, inputs, metrics, thresholds, and release rules.
That judgment determines whether the learned pattern is useful. Machine learning is technical work and decision design at the same time.