AI Combines Signal Types to Build a Fuller Picture
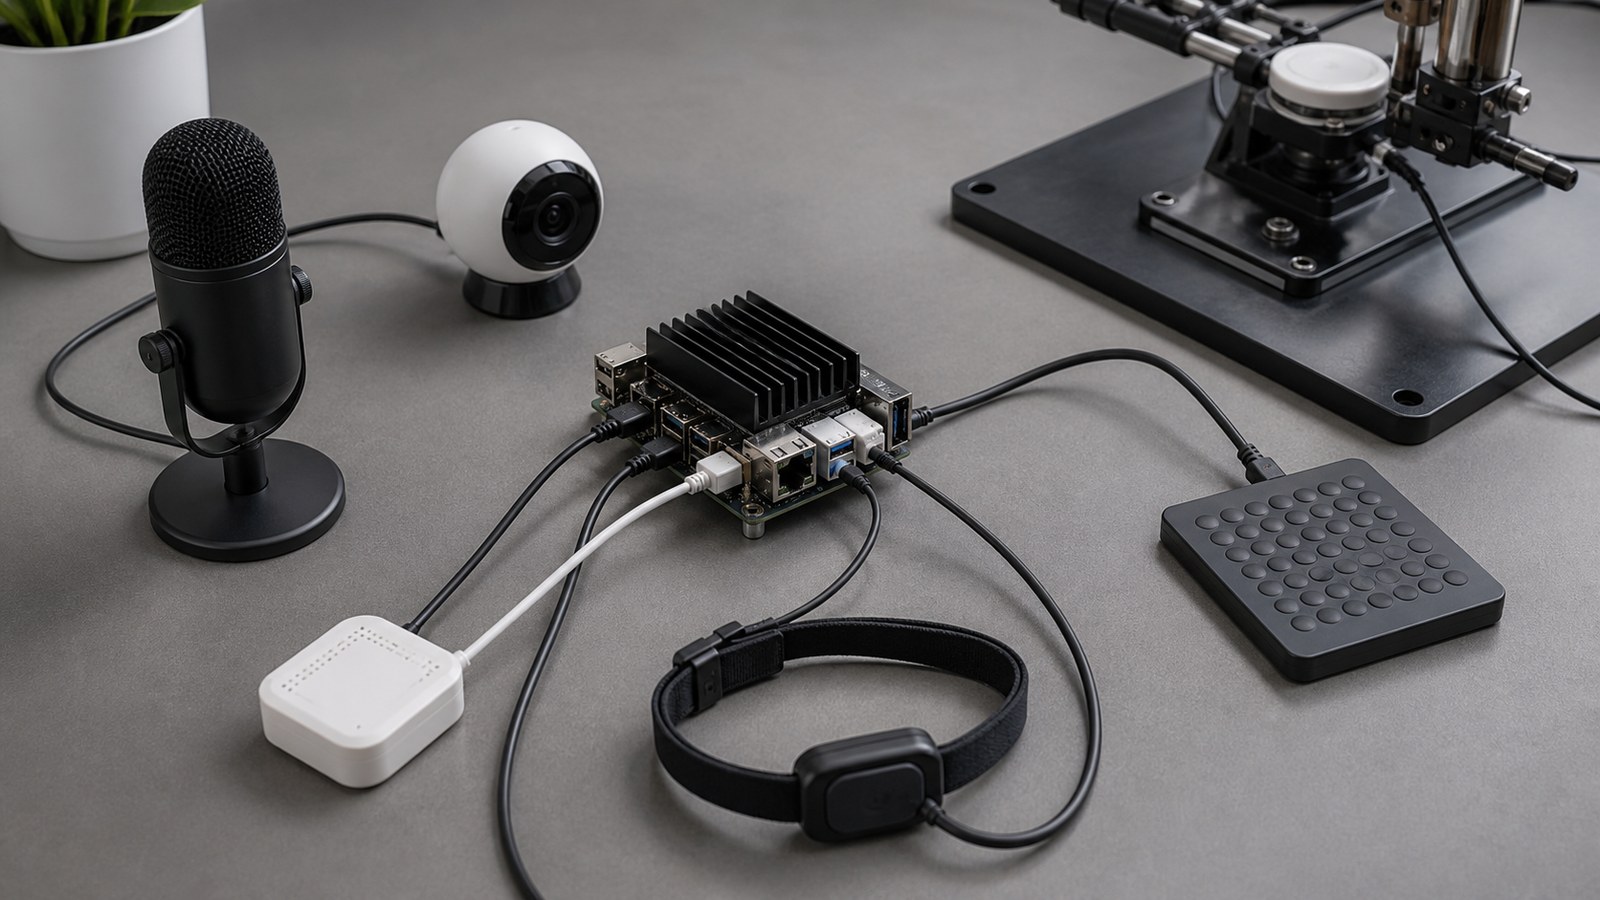
AI combines different signal types when one measurement cannot explain the whole situation. A camera may show shape, a microphone may reveal timing, a wireless trace may show connection behavior, and a sensor may confirm motion or pressure. Multi-modal analysis brings those clues together, but the combined model still needs careful alignment, labeling, testing, and monitoring so the extra data improves understanding instead of adding confusion.
The Signal Purpose Comes First
combined signal analysis should begin with a clear purpose. The AI team needs to know whether the goal is context-aware recognition, forecasting, troubleshooting, or control before collecting or combining data.
That purpose decides which signals matter. It also keeps the multi-modal model from treating every available measurement as equally useful.
Each Signal Should Add Evidence
A signal earns its place when it adds evidence the other signals cannot provide. Extra inputs are helpful only when they clarify the problem.
For this topic, camera frames, audio clips, device readings, network traces, and sensor measurements should be included because they improve the combined evidence stream, not because they make the system look more advanced.
Timing Alignment Matters
Signals often arrive at different speeds. A camera frame, radio packet, audio sample, and sensor reading may not describe the exact same moment.
Alignment helps the multi-modal model compare the right evidence. Poor timing can make true patterns look inconsistent or false patterns look connected.
Sampling Rates Change Detail
Different signals may be sampled at different rates. A fast electrical trace and a slower environmental reading carry different levels of detail.
The AI team should decide how much detail the model needs. Too little detail hides events, while too much detail can add cost and noise.
Missing Signals Need a Plan
Real systems lose data. A sensor may fail, a packet may drop, a microphone may be blocked, or an observation may arrive late.
The multi-modal model should know how to behave when part of the combined evidence stream is missing. Silent failure can be more harmful than a visible gap.
Signal Quality Should Be Scored
Not every measurement deserves the same trust. Noise, drift, poor calibration, low resolution, or weak connection quality can reduce signal value.
Quality scores help the multi-modal model weigh evidence more carefully. They also tell the AI team when a result needs review.
Context Explains the Pattern
A signal pattern makes more sense when the surrounding context is known. Location, device type, time, load, and environment can change interpretation.
Context prevents shallow conclusions. It helps the multi-modal model understand whether a pattern is normal for that situation or truly unusual.
Labels Must Match the Goal
If the model is trained with labels, those labels must match the decision the system is supposed to support.
A weak label can teach the wrong behavior. Clear label rules make combined signal analysis easier to evaluate and improve.
Fusion Can Happen Early or Late
Some systems combine raw signals early, while others process each signal first and combine the results later.
The best fusion method depends on data quality, timing, compute, and the task. There is no single structure that fits every use.
Early Fusion Needs Clean Alignment
Early fusion can be powerful because the model sees signals together from the start. It can learn relationships across inputs.
That benefit depends on clean alignment and consistent formatting. If the inputs are poorly matched, early fusion can amplify confusion.
Late Fusion Keeps Parts Separate
Late fusion lets separate models study separate signals before combining their outputs. This can make troubleshooting easier.
It also helps when one signal is missing or weak. The tradeoff is that some fine-grained relationships may be harder to learn.
Attention Can Weight Evidence
Some models use attention or weighting methods to decide which signal matters most at a given moment.
This helps the multi-modal model adapt when evidence changes. A useful weighting method should still be tested for stability and bias.
Noise Can Travel Through the System
A noisy input can damage the final result if the model gives it too much influence.
Noise handling should happen before and during model evaluation. The AI team should test whether the multi-modal model remains useful when one signal degrades.
Correlation Is Not Proof
Two signals may move together without one explaining the other. Correlation can guide investigation, but it is not the same as cause.
The multi-modal model should be evaluated with realistic cases. Strong-looking relationships can disappear when conditions change.
Edge Cases Reveal Weakness
Edge cases show how the model behaves outside easy examples. They may involve rare events, unusual devices, confusing inputs, or mixed evidence.
These cases are valuable tests. They show whether the combined evidence stream is robust or only works in clean situations.
Privacy Should Shape Collection
Signal systems can capture sensitive behavior, location, voice, health, device, or operational information.
Privacy planning should guide what is collected, stored, and shared. A useful model should not depend on careless data handling.
Security Protects the Evidence
Signal inputs can be spoofed, altered, blocked, or poisoned. A model that trusts bad evidence can make bad decisions.
Security checks should protect data collection, storage, model access, and updates. Trust depends on the full pipeline.
Compute Limits Affect Design
Combining signals can increase processing cost. More inputs may require more memory, bandwidth, battery, storage, and model capacity.
The AI team should measure those limits early. A model that cannot run in the needed environment is not ready.
Latency Can Decide Usefulness
Some signal tasks need fast response. A delayed result may be technically accurate but operationally weak.
Latency should be measured with the full pipeline included. Collection, transfer, processing, fusion, and output delivery all add time.
Interpretability Helps Review
When several signals shape one output, people may need help understanding why the model responded.
Interpretability tools can show which inputs influenced a result, but they should be treated as aids, not perfect explanations.
Baselines Keep Claims Honest
A simple baseline helps show whether combined signal analysis truly improves the outcome. The baseline might use one signal, a rule, or an older model.
If the combined approach does not beat the baseline enough to justify its cost, a simpler system may be better.
Metrics Should Match the Task
The right metric depends on the task. Accuracy, recall, false alarms, latency, stability, and cost may all matter in different ways.
Metrics should reflect the actual decision. A single score rarely explains the whole value of the multi-modal model.
Segment Testing Finds Gaps
Overall performance can hide weak spots. The system may work well for one device, signal type, time period, or environment and fail for another.
Segment testing finds those gaps. It shows where the combined evidence stream is strong and where more data or tuning is needed.
Drift Can Change Performance
Signal environments change over time. Devices update, users move, channels shift, sensors age, and operating patterns evolve.
Drift monitoring helps the AI team catch those changes. It shows when retraining, recalibration, or new data collection may be needed.
Documentation Makes the System Usable
Documentation should explain what signals are used, how they are aligned, what labels mean, and how performance is measured.
Good documentation makes the multi-modal model easier to maintain. It also helps people understand the limits of the combined evidence stream.
Human Review Needs Clear Rules
Some outputs should go to human review, especially when evidence is uncertain or consequences are meaningful.
Review rules should be planned before launch. They keep the multi-modal model useful without asking it to decide every difficult case alone.
Fallback Behavior Matters
When a signal is unavailable or confidence is low, the system should have a fallback behavior.
Fallbacks may include waiting, using a simpler rule, asking for review, or entering a safe state. The plan should be explicit.
Deployment Should Match the Environment
A model tested in a clean lab may behave differently in a busy network, noisy room, moving vehicle, factory floor, or outdoor site.
Deployment tests should reflect real conditions. The combined evidence stream must be judged where it will actually be used.
Operational Feedback Improves the Model
After launch, user reports, error reviews, alerts, and performance logs can reveal where the model needs improvement.
Feedback should be organized rather than scattered. It can guide better data collection and safer updates.
Versioning Supports Comparisons
Model, dataset, configuration, and preprocessing versions should be tracked. Small changes can alter results.
Versioning helps the AI team compare outcomes and roll back if needed. It turns updates into controlled work.
A Useful Model Reduces Confusion
combined signal analysis is valuable when it makes a situation easier to understand. More inputs should lead to clearer decisions, not more uncertainty.
The practical test is whether the multi-modal model helps people act with better evidence. If not, the design needs more review.
Good Systems Explain Limits
A trustworthy system says where it works and where caution is needed. Limits may involve signal quality, coverage, training data, or operating conditions.
Clear limits prevent misuse. They also help the AI team decide what to test next.
The Combined View Needs Discipline
A combined view can feel persuasive because it includes many signals. That makes disciplined testing even more important.
The combined evidence stream should earn trust through repeatable results. It should not rely on the appearance of complexity.
Maintenance Is Part of the Design
Signal systems need maintenance after launch. Sensors, channels, software, users, and goals can all change.
Maintenance should include monitoring, review, documentation, and planned updates. The multi-modal model stays useful only if it stays current.
Final Practical Takeaway
combined signal analysis works best when every signal has a job, every metric has a purpose, and every result can be checked.
The goal is not to collect the most data. The goal is to build a signal system that gives clearer evidence for the decision at hand.
Training Data Should Match Reality
Training examples should resemble the real conditions where the multi-modal model will operate. Clean examples are useful, but they are not enough by themselves.
The AI team should include difficult cases, ordinary cases, and borderline cases. That range helps the model avoid fragile behavior.
Conflicting Evidence Needs Rules
Different signals can disagree. One input may point toward a problem while another looks normal.
The multi-modal model needs rules or learned behavior for conflict. Otherwise the combined evidence stream can become harder to trust when evidence is mixed.
Confidence Should Reflect the Full View
Confidence should consider the quality of all important inputs, not just the final model score.
If a key signal is weak, missing, or noisy, the result should show that uncertainty. Honest confidence is more useful than forced certainty.
Testing Should Include Ablation
Ablation testing removes one signal at a time to see how much it contributes. This reveals whether each input is actually helping.
Ablation keeps the design honest. It can show when a simpler system performs nearly as well as the full model.
Model Updates Need Comparison
When the model changes, teams should compare old and new behavior on the same test cases.
This protects against accidental regressions. A new version should improve the target outcome without weakening important edge cases.
Clear Outputs Help Users Act
A model output should be clear enough for people or downstream systems to use. A vague score can create hesitation instead of better action.
Clear outputs include labels, confidence, timing, and recommended next steps when appropriate. The result should fit the workflow.
Review Logs Create Learning Loops
Review logs show where users agreed with the system, corrected it, or ignored it. Those patterns can guide future improvements.
Logs should be gathered carefully and respectfully. They help the AI team improve the multi-modal model without guessing.
Final Deployment Check
Before deployment, the AI team should confirm data quality, timing, missing-signal behavior, metrics, fallback rules, and monitoring.
That final check keeps combined signal analysis practical. It turns a promising model into a system that can be operated and improved.